MetaboAnalyst 7.0 is a comprehensive web ecosystem for metabolomics, lipidomics, and multi-omics data analysis. Building on a decade-long foundation in raw spectra processing, multivariate statistics, pathway topology, and biomarker discovery, Version 7.0 expands to decode the broader chemical interface of life—integrating lipids, spatial tissue context, and environmental signals (exposome, diet, and microbiome). The platform organizes 28 specialized modules across 7 application domains, from statistics, targeted and global metabolomics to spatial metabolomics, lipidomics, exposomics and microbiomics.
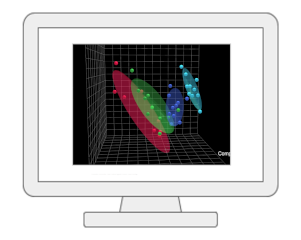
Univariate tests (fold change, t-tests, volcano plot, ANOVA, correlation), multivariate methods (PCA, PLS-DA, sPLS-DA, OPLS-DA), clustering (dendrogram, heatmap, k-means, SOM) and classification (random forest, SVM).
Associations between metabolites and phenotypes adjusted for covariates by linear models, with PCA and heatmaps; two-way ANOVA, ASCA and MEBA for two-factor and time-series designs.
ROC curve analysis of single biomarkers, and multi-feature panels built with five methods (linear SVM, PLS-DA, random forests, Elastic Net and logistic regression), cross-validated, with clinical covariates as predictors and prediction of new samples.
Sample size planning: a priori power from expected effect sizes, or from pilot data by the effect-size model (SSPA), resampling for the planned test, a biomarker learning curve or pathway-level power.
Metabolite set enrichment analysis of a compound list or a concentration table against about 13,000 metabolite sets: pathways, disease signatures, locations and chemical classes.
Pathway enrichment and topology analysis with interactive visualization for 26 organisms; Joint Pathway Analysis integrates gene expression results of the same conditions.
Metabolites, genes or KEGG orthologs explored in knowledge-based networks, or debiased sparse partial correlation (DSPC) networks computed from a data table.
Consistent features across several studies under comparable conditions, by combining p values, vote counting or merging the data sets.
Raw LC-MS spectra (mzML, mzXML, mzData) processed by an auto-optimized workflow or asari, with DDA or SWATH-DIA MS/MS spectra for compound annotation.
MS/MS spectra, a single DDA peak list or an MSP file from MS-DIAL or MZmine, annotated against experimental and in silico spectral libraries.
Pathway activity predicted directly from high-resolution MS peaks by mummichog or GSEA, without prior identification, for 26 organisms.
Robust functional profiles across global metabolomics studies, by combining the pathway results of independent studies or pooling the peaks of complementary platforms.
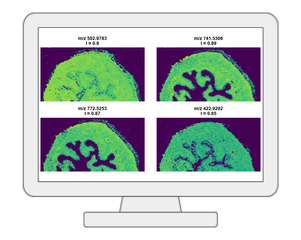
MALDI or DESI imaging m/z tables with coordinates and regions: Moran's I quality control, tissue maps, pseudobulk comparison of regions, pathway-guided annotation and compound sets.
Spatial tables of named metabolites or lipids: name mapping, normalization, tissue maps, pseudobulk differential analysis between regions, compound-set maps and enrichment.
Spatial metabolomics with transcriptomics or proteomics of the same section: joint clustering, cross-omic co-localisation, pseudobulk comparison and joint pathway analysis.
Exports of SCiLS Lab, METASPACE and 10x Visium converted into the spatial tables; regions derived by segmentation, sections merged or paired with LC-MS data of the same tissue.
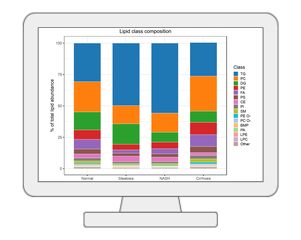
Lipid classes and sum-composition species assigned to MS/MS spectra from LipidBlast in silico spectra; molecular species only when the spectrum separates the isomers.
A table of lipid species with sample groups: names parsed and normalised, then class composition, chain length and unsaturation, and species statistics.
LIPID MAPS categories, classes and lipid pathways enriched among significant lipids or associated with a concentration table, each name matched at its own level.
Imaging m/z matched to lipid species at sum-composition level, summarised as lipid-class tissue maps, regional class statistics and chain length profiles.
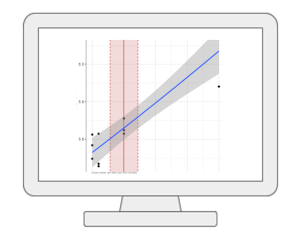
Suspect screening of MS1 features (PubChemLite, NORMAN SusDat, Blood Exposome Database) with confidence levels, and MS/MS annotation against diet and exposure compounds.
Dose-response curve fitting for repeated dosing or continuous exposure, with feature-level benchmark doses (BMD) and the metabolomic point of departure.
Food intake biomarkers, dietary patterns, food composition, chemical exposures, pollutants and drug pathways enriched among significant compounds or in a concentration table.
Two-sample Mendelian randomization between SNP-tagged metabolites from mGWAS and disease outcomes, with SNP harmonization, MR diagnostics and literature evidence.
MS/MS spectra annotated with gut microbial metabolites (MiMeDB, Exposome-Explorer, KEGG gut bacterial pathways), with the evidence of microbial involvement and source context.
Negative-mode LC-MS peak tables screened for the m/z markers of 59 bacterial taxa, with decoy-based significance and group comparison of taxon scores.
Microbial functions, chemical classes, producing genera and gut bacterial pathways enriched among significant compounds or in a concentration table.
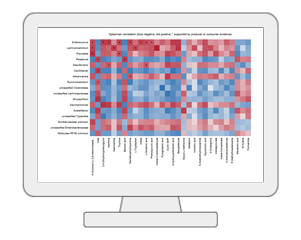
Paired microbiome and metabolome profiles: taxon-metabolite correlations weighed against producer and consumer evidence rank candidate microbes, with heatmaps, networks and concordance.
Data utilities: Compound ID Conversion, Batch Effect Correction and Merging Duplicate Records
|
|
Training & Pro ServicesAccess self-paced Omics Data Science training coupled with AI, tools and our Omics Data Science book. For organizations requiring enhanced capabilities, our Pro version runs on cloud or on your server with dedicated support and custom integrations. |